MMM vs. MTA: Two Different Jobs, Not Competing Methods
Media mix modeling vs attribution isn’t really a contest, and treating it like one is what causes the actual problem: two numbers that don’t match, shown to the same leadership team, with nobody quite sure which one to trust.
Once you’re past the basics of what each measures, the real work is knowing exactly why they’ll diverge and having a process ready for when they do, not being surprised by it.
Strategic vs. Tactical: The Actual Division of Labor
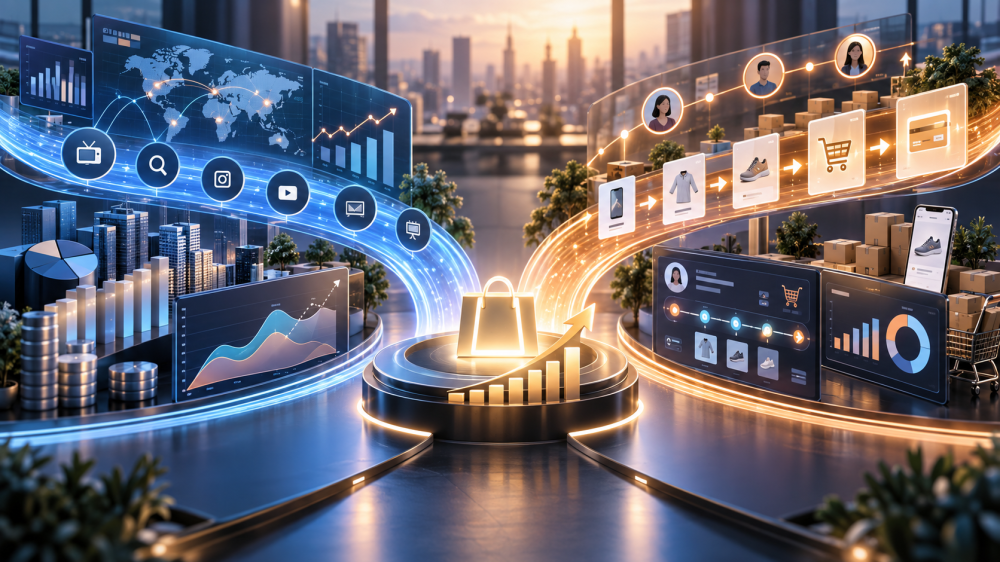
MMM operates on aggregate data, spend and revenue over weeks or months, and answers the strategic question: how should budget be allocated across channels overall.
MTA operates on individual-level data, specific touchpoints in specific customer paths, and answers the tactical question: which ad set, creative, or campaign deserves this week’s budget within whatever envelope MMM has already set.
Neither replaces the other because neither is built to answer the other’s question. MMM won’t tell you which of your twelve Meta ad sets to pause tomorrow.
MTA won’t tell you whether the whole Meta budget should grow or shrink next quarter.
Why They’ll Never Agree Exactly, and That’s Fine
The disagreement isn’t a bug in either model, it’s structural.
- MMM typically measures effects with a 4 to 8 week lag, capturing adstock and carryover, the slow-building effect of sustained spend.
- MTA defaults to a same-session-to-7-day window, built to catch fast, trackable conversions.
Two models measuring different time horizons on the same channel will produce different numbers even when both are working correctly.
The gap shows up concretely and often.
In one documented case, Facebook MTA reported a $3.20 CPA, while backing out Facebook’s incremental contribution from the MMM implied a $5.80 CPA on the same spend. That $2.60 gap wasn’t a modeling error.
It reflected real influence MTA structurally can’t see, brand awareness, word-of-mouth, competitive context, that MMM captures because it’s looking at the aggregate outcome rather than a traceable click path.
Disagreement here is information, not failure, provided the underlying data feeding both models is actually consistent to begin with.
The Four Shapes Disagreement Takes
Once data quality is confirmed, and it’s always worth confirming that first, a genuine model disagreement tends to fall into one of four recognizable patterns, each with a different fix.
MTA credits a channel MMM says did little.
This is most often a demand-capture channel getting credit for demand something else actually created. Branded search is the classic example, it converts beautifully in MTA and barely registers as incremental in MMM. The fix: trust MMM’s read on the channel’s real contribution to the total, but keep using MTA to manage that channel’s day-to-day efficiency, since it’s still a useful tactical signal even when it’s a poor strategic one.

MMM credits a channel MTA barely registers.
Usually upper-funnel or offline activity leaving no trackable digital touchpoint. Before accepting this at face value, check whether the gap is real or a coverage artifact, an attribution setup that only records clicks will always undervalue an impression-heavy channel, regardless of what’s actually happening.
Both agree on direction, disagree on size.
This is the healthy, unremarkable case, both models see the channel moving the same way, just by different magnitudes given their different time windows and data granularity. It generally needs no intervention.
Both disagree on direction entirely,
one model says a channel is growing in value, the other says it’s shrinking, is the case that actually warrants concern, and it’s usually a data pipeline problem rather than a genuine modeling disagreement. Reconcile spend and conversion totals between the two systems within a tight tolerance before assuming the models themselves are in real conflict.
How to Present Both in the Same Board Deck Without Contradicting Yourself
The instinct to average two disagreeing numbers into one clean figure for a slide is exactly the wrong move.
- Reconcile, don’t average: show the MTA view and the MMM view side by side, on the same dashboard, same date range, same revenue definition, each clearly labeled for what it is.
- A single blended “attribution number” with no indication of which model produced it is how a measurement story loses credibility with finance the moment someone asks a follow-up question.
With 62% of CMOs already naming ROI proof to finance as their single biggest challenge, a blended number that can’t survive scrutiny is a bigger risk than two honest numbers that don’t perfectly agree.
Put a reconciliation cadence behind this rather than treating it as a one-time exercise.
A monthly review, owned jointly by whoever manages media buying and whoever owns the measurement stack, comparing the two models’ outputs and applying the four-pattern framework above, keeps disagreement from silently accumulating into a full quarter of budget decisions built on an unresolved contradiction.
- The more advanced version of this loop feeds a clean causal result, like a geo-lift test, back into the MMM as a Bayesian prior, updating the model’s belief about that channel’s true contribution rather than leaving the regression to guess from correlation alone.
- When the two genuinely disagree on direction and the data checks out, an incrementality test is the tiebreaker, not another dashboard, since it’s the one method in the stack built to answer the causal question neither MMM nor MTA can fully resolve on its own.
If you want help building a reconciliation process between your own attribution and measurement stack, book a live AdBeacon demo.
—-
FAQ
Why do MMM and MTA give different numbers for the same channel?
Structurally, not accidentally. MMM measures effects over a 4 to 8 week lag, capturing slow-building brand and carryover effects. MTA defaults to a same-session-to-7-day window built for fast, trackable conversions. Different time horizons on the same channel will produce different numbers even when both models are working correctly.
Should I average my MMM and MTA numbers together for reporting?
No. Averaging or blending the two into a single figure hides which model produced it and makes the number impossible to defend under scrutiny. Show both side by side, clearly labeled, with the same date range and revenue definition, and reconcile the difference through investigation rather than arithmetic.
What does it mean when MTA credits a channel that MMM says isn’t contributing much?
Usually a demand-capture channel, commonly branded search, is getting credit for demand another channel actually created. Trust MMM’s read on that channel’s real contribution to the total, but MTA is still useful for managing that channel’s tactical efficiency day to day.
How often should MMM and MTA outputs be reconciled?
Monthly is a reasonable cadence for most brands, owned jointly across media buying and measurement rather than left to happen informally. This catches disagreement early instead of letting an unresolved contradiction drive a full quarter of budget decisions.
What should I do when MMM and MTA disagree on the direction of a channel’s performance, not just the size?
First, verify the underlying spend and conversion data match between the two systems within a tight tolerance, this is usually a data pipeline issue, not a real modeling disagreement. If the data checks out and the disagreement persists, an incrementality test is the appropriate tiebreaker.
Sources
- Improvado: MMM vs MTA, When to Use Each Method in 2026
- TapClicks: Marketing Attribution in 2026, Why Multi-Touch and Marketing Mix Modeling Have to Work Together
- Roivenue: MMM vs. MTA, What’s the Difference and Which Do You Need?
- Digital Applied: MMM vs MTA vs Lift Tests 2026, The Measurement Matrix